Abstract
Instruction-based text-to-speech (TTS) enables natural-language control of speaking style without reference audio,
but a comparable resource has been unavailable for Vietnamese despite the language's tonal prosody and substantial
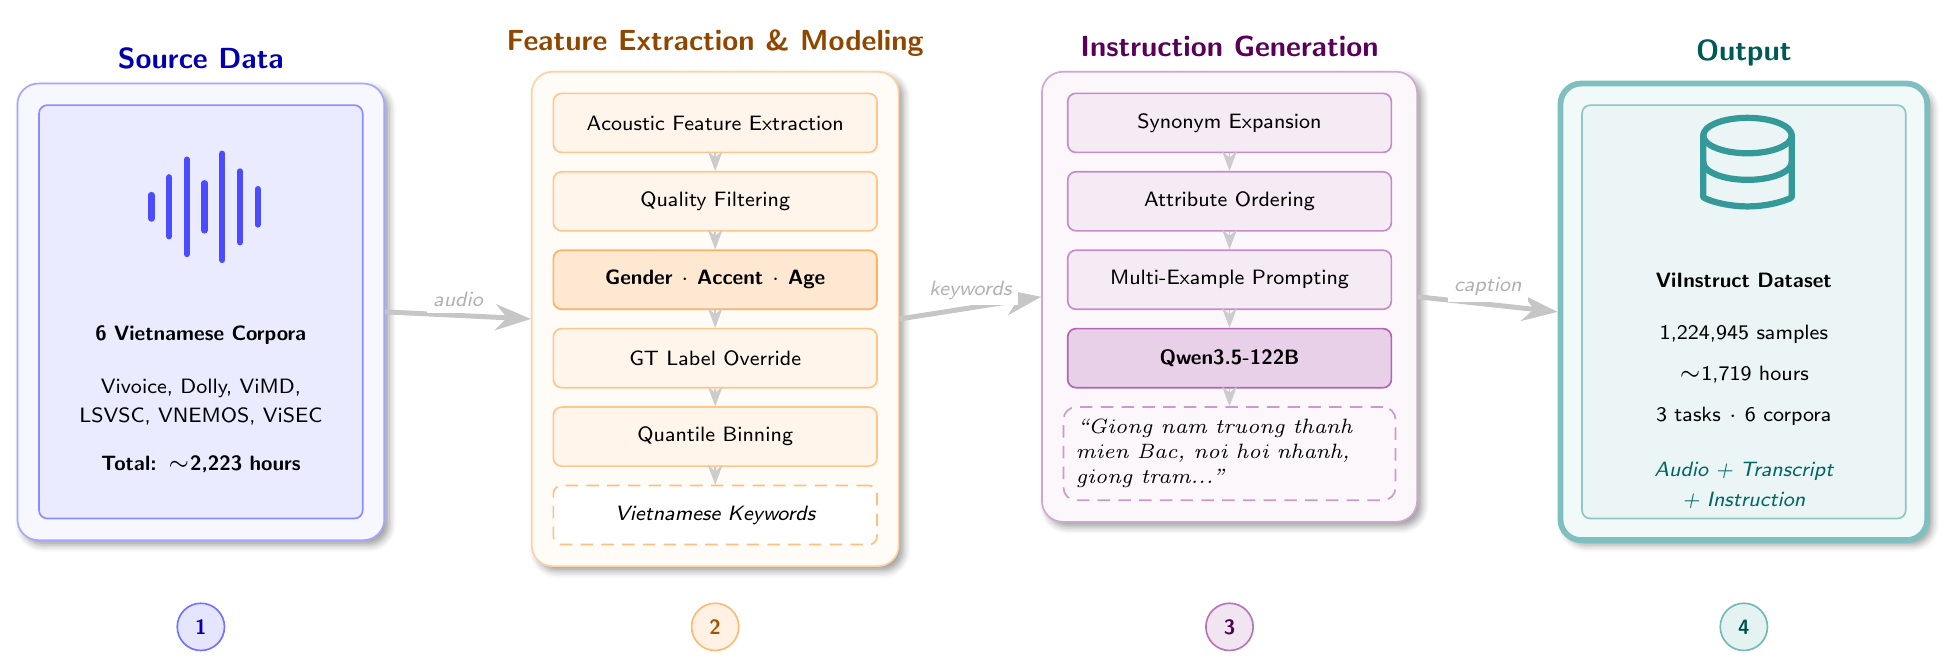
regional variation. This paper introduces ViInstruct, the first large-scale Vietnamese dataset for
instruction-based TTS, comprising approximately 1,718 hours of speech and 1,224,945
utterance-instruction pairs. We also provide a standardized benchmark to support reproducible evaluation of
controllable Vietnamese TTS. ViInstruct establishes a practical foundation for instruction-following speech synthesis
research in Vietnamese, a low-resource tonal language.
Table IV: Main Automatic Evaluation Results
Lower is better for CER, WER, and Fail. Higher is better for UTMOS and adherence metrics.
Categorical adherence is reported with macro-F1. Source audio is reported only for speech-quality metrics.
For Layer-2 adherence, source audio is marked N/A because reference instructions are derived from
the annotation pipeline and are not an independent target.
| Metric |
Source Audio |
Parler-TTS |
CapSpeech NAR |
| Speech Quality |
|
|
|
| CER (%) ↓ |
0.96 |
3.19 |
0.85 |
| WER (%) ↓ |
2.15 |
4.80 |
1.55 |
| UTMOS ↑ |
2.95 |
2.54 |
2.65 |
| Fail. Rate (%) ↓ |
0.0 |
0.57 |
0.0 |
| Instruction Adherence |
|
|
|
| Gender F1 (%) ↑ |
N/A |
84.83 |
100.00 |
| Age F1 (%) ↑ |
N/A |
49.94 |
52.82 |
| Accent F1@General (%) ↑ |
N/A |
48.56 |
77.48 |
| Accent F1@Accent Set (%) ↑ |
N/A |
38.82 |
72.37 |
| Bin Acc Avg (%) ↑ |
N/A |
36.46 |
66.55 |